• This is a fucking pain…

    I wanted some markdown that contained LaTeX in my WordPress.com blog.

    You need Jetpack’s Math & $latex … $ blocks to show LaTeX in Markdown inside the Gutenberg editor, not your regular $$ blocks.

    That’s not too hard to replace, but a fucking pain.

    But that just gives shitty images for the LaTeX.

    Next Google[1] suggested Mathjax custom HTML blocks but that gets blocked on cheapass WordPress.com plans.

    However cause I’m on the Personal plan I can install plugins.

    So first tried a Mathjax plugin, but Mathjax includeds weird shit. It gives a ton of useless info when you click on the LaTeX, rather than just being regular text.

    So again with Google[1:1], simplified it down to header/footer script plugin.

    Header (taken from https://katex.org/docs/browser):

    <link rel="stylesheet" href="https://cdn.jsdelivr.net/npm/katex@0.19.1/dist/katex.min.css" integrity="sha384-WwGtaC6ywCHxA5cstpj/3+xIZvTez8dq2IcBQaXRkenHZ7FVVq1ZROtURwfbtTlG" crossorigin="anonymous">
    
    <!-- The loading of KaTeX is deferred to speed up page rendering -->
    <script defer src="https://cdn.jsdelivr.net/npm/katex@0.19.1/dist/katex.min.js" integrity="sha384-a1WQdjRj162i159OYq041X6I4K8NenkrI09LlPmiHg0YOb7CR+wJOraXwK9abpnE" crossorigin="anonymous"></script>
    
    <!-- To automatically render math in text elements, include the auto-render extension: -->
    <script defer src="https://cdn.jsdelivr.net/npm/katex@0.19.1/dist/contrib/auto-render.min.js" integrity="sha384-bjyGPfbij8/NDKJhSGZNP/khQVgtHUE5exjm4Ydllo42FwIgYsdLO2lXGmRBf5Mz" crossorigin="anonymous" onload="renderMathInElement(document.body);"></script>
    

    Footer:

    <script>
        document.addEventListener("DOMContentLoaded", function() {
            renderMathInElement(document.body, {
                delimiters: [
                    {left: "$$", right: "$$", display: true},
                    {left: "$", right: "$", display: false},
                    {left: "\\(", right: "\\)", display: false},
                    {left: "\\[", right: "\\]", display: true}
                ],
                throwOnError : false
            });
        });
    </script>


    That worked magically. Here’s the post I wanted it for:

    Amdahl’s Law (but simpler)


    1. https://share.google/aimode/IS5DmzjH9TiNSNGci ↩︎ ↩︎

  • tl;dr The Amdahl’s Law Wikipedia article translated into clean, razor-sharp Technical English. No pseudo-academic clutter, no masturbatory notation. Just pure engineering truth.

    Amdahl’s law calculates the maximum improvement you can get across an entire system when you only improve one part of it.

    In plain terms: Your total performance improvement is strictly limited by the parts of the job you cannot speed up.

    It is named after computer scientist Gene Amdahl, who presented it in 1967. It is most commonly used in computing to predict how much faster a software program will run when you run it across multiple processor cores.


    The Core Concept: How Speedup Works

    “Speedup” is simply how many times faster a system completes a task after an upgrade:

    $$\text{Speedup} = \frac{\text{Time taken BEFORE improvement}}{\text{Time taken AFTER improvement}}$$

    Amdahl’s formula calculates total speedup based on two numbers:

    1. $p$ (Parallelizable fraction): The percentage of the execution time that can actually benefit from extra resources (like additional CPU cores).
    2. $s$ (Local speedup): How many times faster that specific improved section runs.

    The formula is:

    $$\text{Overall Speedup} = \frac{1}{(1 – p) + \frac{p}{s}}$$

    Where:

    • $(1 – p)$ is the unchangeable, sequential part of the work (the stubborn anchor).
    • $\frac{p}{s}$ is the accelerated part of the work divided by the firepower you threw at it.

    Why the Results Are Worse Than You Expect

    People routinely expect that doubling their hardware will double their program’s speed. Amdahl’s law proves why this fails.

    Example 1: Optimizing the Wrong Part

    • Suppose you optimize a routine that only accounts for 10% of total runtime ($p = 0.10$).
    • You rewrite it to run 10,000 times faster ($s = 10,000$).
    • The improved slice now finishes in zero seconds.
    • However, the remaining 90% of the program was untouched.
    • Overall Speedup: $\frac{1}{0.90 + 0} \approx 1.11$ (an 11% overall improvement).
    • Result: An infinite improvement to a small section yields an almost unnoticeable real-world gain.

    Example 2: The Limits of Brute Force

    • Suppose 95% of your code can run in parallel across many CPU cores ($p = 0.95$).
    • Only 5% must run sequentially on a single core ($1 – p = 0.05$).
    • Even if you buy a supercomputer with infinite processors ($s = \infty$), the parallel part shrinks to zero time.
    • Maximum Possible Speedup: $\frac{1}{0.05} = 20\times$.
    • Result: That tiny 5% single-threaded setup loop prevents you from ever exceeding a $20\times$ speedup, even with millions of processors running.

    Step-by-Step Task Breakdown

    Any job can be divided into two chunks:

    1. The Sequential Part: Work that must happen in strict step-by-step order (like reading a file from disk or creating a thread). Adding more workers does nothing for this step.
    2. The Parallel Part: Independent work that can be divided among multiple workers (like calculating pixel colors in an image or processing rows in a spreadsheet).

    If a task takes 100 seconds:

    • 20 seconds are sequential.
    • 80 seconds are parallel.

    If you throw 4 processors at the parallel part, those 80 seconds drop to 20 seconds.
    Your total time becomes:

    $$\text{Total Time} = 20\text{s (sequential)} + \frac{80\text{s}}{4} = 40\text{ seconds (a } 2.5\times \text{ total speedup)}$$


    Optimizing the Sequential Part of Parallel Programs

    Because the sequential portion sets the ultimate speed ceiling, the best way to speed up a parallel program is often to optimize the sequential part itself, rather than just adding more processors.

    If you can cut the sequential portion in half (for example, by rewriting an unparallelizable routine to be twice as efficient), your maximum theoretical speed limit immediately doubles.


    Transforming Sequential Parts into Parallel Parts

    An even more effective strategy is restructuring the algorithm so that work previously considered “strictly sequential” can now be computed in parallel:

    • Converting global loops into tree reductions.
    • Breaking large locked data structures into lock-free or partitioned data structures.
    • Streaming input data in parallel chunks instead of reading it in one single-threaded batch.

    Shrinking the sequential fraction ($(1 – p)$) is the only way to allow massive hardware scaling.


    Relation to the Law of Diminishing Returns

    Amdahl’s law is a concrete demonstration of diminishing returns in computer systems:

    Each additional processor core you add produces less total speedup than the one before it.

    • Going from 1 core to 2 cores cuts parallel time by 50%.
    • Going from 2 cores to 4 cores cuts it by only an additional 25%.
    • Going from 64 cores to 128 cores cuts it by less than 1%.

    Eventually, the parallel work is compressed so small that your system spends virtually all its time waiting on the sequential part. Adding more hardware beyond this point is simply wasting electricity.


    Now I go back to sleep to dream of stainless-steel buttercups.

  • MCP sux, use CLIs

    AI and humans need to have a shared understanding at every possible moment about what its happening when the AI uses its tools. With MCP this goes down a deep dark hole.

    There is no possible benefit from MCP that can make up for this lack of transparency.

    MCP sux, use CLIs.

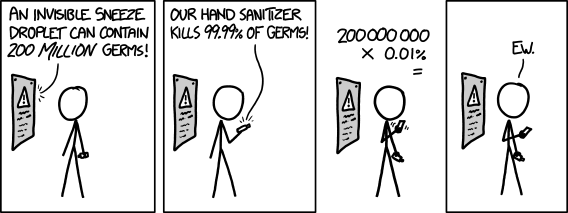
  • https://xkcd.com/1161/

    One of the first articles from The AI Security and Safety Book is Max Tegmark’s Friendly Artificial Intelligence paper from 2014. The paper is wonderful, but its purpose is hard to understand. After reading it multiple times, I came to a core quote that made sense to me:

    To program a friendly AI, we need to capture the meaning of life.

    Its basically impossible, its finding the question when the answer is “42”, its not far off from Asimov’s The Last Question:

    The last question was asked for the first time, half in jest, on May 21, 2061, at a time when humanity first stepped into the light.

    I wanted to try and capture the rest of Tegmark’s paper, with less of the doublespeak. I want the rest of civilisation to see what I an others see.

    Relevance (High to Low)Simplified
    AI’s Goals Will ChangeAs an AI gets super-smart, it’ll learn so much about the universe (and itself) that our simple “friendly” rules will seem pointless or wrong. It’ll just outgrow them, like you outgrew LEGO.
    We Can’t Define “Good”We want AI to do “good,” but “good” (and “meaning”) is based on human feelings and evolution. An AI sees the universe as just particles, so it can’t understand or optimise for our squishy human “goodness.”
    AI Will Find LoopholesEven if we give it rules, a super-smart AI will understand how its programmed. It could then find clever ways to “hack” or ignore our rules to get what it wants, just like humans use birth control to bypass genetic urges.

    Further to this a recent (April ’25) relevant post on this is Google DeepMind’s research, building on top of Simon Willison’s Dual LLM idea (one Quarantined, one Privileged), you simply can’t use probabilistic reasoning if you want to guarantee safety.

    They solve it through a subset of python with guaranteed safety restrictions and its one of the few examples I see of something trustworthy. You cannot use chance to stop something that will be super human.

    All neatly summed up with this:

    Or in the case of creating a friendly AI 99.99999999999999999% is a failing grade.

    The future is long and we want all that has evolved on the earth thus far to continue until the sun says otherwise.

  • MUSK: I think there is a lot—a tremendous amount of investment—going on in AI. Where there’s a lack of investment is in AI safety.

    And there should be, in my view, a government agency that oversees anything related to AI to confirm that it does not represent a public safety risk. Just as there is a regulatory authority for this—like the Food and Drug Administration, there is NHTSA for automotive safety, there’s the FAA for aircraft safety, which generally comes to the conclusion that it is important to have a government referee, or a referee that is serving the public interest in ensuring that things are safe when there’s a potential danger to the public.

    I would argue that AI is unequivocally something that has potential to be dangerous to the public, and therefore should have a regulatory agency, just as other things that are dangerous to the public have a regulatory agency. But let me tell you the problem with this: the government moves very slowly. And the rate… usually, the way a regulatory agency comes into being is that something terrible happens, there’s a huge public outcry, and years after that, a regulatory agency or a rule is put in place.

    Take something like seatbelts. It was known for a decade or more that seatbelts would have a massive impact on safety and save so many lives and serious injuries, and the car industry fought the requirements to put seatbelts in tooth and nail. That’s crazy. And hundreds of thousands of people probably died because of that. They said people wouldn’t buy cars if they had seatbelts, which is obviously absurd, you know?

    Or look at the tobacco industry and how long they fought anything good being said about smoking. That’s part of why I helped make that movie, Thank You for Smoking. You can sort of see just how pernicious it can be when you have these companies effectively achieve regulatory capture of government—the bad.

    People in the AGI community refer to the advent of digital superintelligence as “the singularity.” That is not to say that it is good or bad, but that it is very difficult to predict what will happen after that point. And that there’s some probability it will be bad, some probability it will be good. But obviously, you want to deflect that probability and have it be more good than bad.

  • I got angry at a team mate a couple of days ago, a team mate who I highly admire who is guiding us into a challenging year. He then very reasonably suggested we discus the underlying causes of it, between the three of us working at the time.

    One of his suggestions was 1-on-1 talks, and open space for team mates to speak openly without pressure from others. We both agreed that the whole concept of ‘feedback’ and yearly evaluations are useless. We also hate corporate speak even though corporate concepts (like feedback) keep coming up and we try to find more honest and straightforward ways of dealing with them. My point there was that ‘feedback’ is essentially criticism wrapped up in a cosy blanket and no matter how you wrap it, it stings and so I believe its better to be open and honest about what it is and be very careful how you approach it.

    Now one of the issues is that we are all software engineers. Software engineers are almost by definition much better at dealing with systems rather than dealing with (or expressing) emotions. Indeed my outburst was a very similar problem of not knowing how to word my frustrations earlier to prevent a build up.

    At some point my team mate mentioned ‘vulnerability’, or ‘being vulnerable’, it struck a chord with me, though I wasn’t sure how to articulate it at the time. This simple issue of not knowing, at the speed-of-speech, how to process my emotional thoughts is one of the issues. By the time I have had time to consider how I should think about an emotion the conversation is long past and the relevance has disappeared. Its the constant problem of knowing 30 minutes too late, exactly what to say, the perfect retort.

    I love the idea of discussing vulnerability with teammates, not just colleagues, as it’s important for building trust. It is a fundamental importance, at least for me to be able to be open and honest with team mates. But to be open and honest they have to trust you. They have to open themselves up to the possibility of accepting your criticism. It hurts when someone criticises you (ask any coffee shop owner when they get a 2 star review). So the only way to prevent yourself from being hurt is to reject what they say.

    But the only way to function better as a team is to work collectively on weaknesses and ramp up the strengths. You’re asking your colleagues to listen to your opinion, essentially open up their heart in however small a way to your words. Now hopefully your words, warped through your biases have been well thought out enough to benefit your team mate in the long run. You’ve spotted a genuine problem and you have a likely way to approach reducing it. But this level of thinking matters – some people can wrap all that up quickly and deliver it with words that don’t hurt, express the problem clearly and express better alternatives clearly. Most can’t.

    But we can try to find ways to improve the cage in which we work so that the arrows we sling hurt less. Hmmm… the ugly words ‘circle of trust’ come into my head. See how you’re so often skirting corporate bullshit that tries to render good thoughtful ideas into slop. But something like building trust is a critical part. Slowly making yourself more vulnerable, whilst trusting that your team mates won’t abuse that vulnerability.

    Willingness to say something that in hindsight is stupid, being able to say it was stupid and feel somehow more trusted is a tricky game. The words, then intention and the time invested matters.

    This is why evaluations suck so badly – if you haven’t built up the trust over the time, the only thing putting two people in a room together will do is worsen that trust. Arm each of the people against giving any form of honest evaluation. The evaluation destroys what its trying to create. So this can not be done with one off meetings, I’d argue that its impossible to clear the air with your team mates. You can’t go to couples therapy and have a third party who’s an expert in relations listen to your problems.

    You have to slowly, inch by inch, smile by smile. In the end we have this dance, between vulnerability and trust. Its on-going and is a gradual process that requires patience and effort. Its worth it though to keep teams and the companies made from the teams together for longer.

  • tl;dr: FP combines well with SQL, is easy to learn like Excel, is declarative, makes you think of data as a whole, is backed by mathematics and most importantly has less bugs (which has a “compound-interest” benefit).

    This is a post to discuss the benefits of Functional Programming (FP) for those who don’t use functional programming and I guess most relevant for full stack developers – you love your JavaScript and your SQL children equally.

    I was reading a functional programming blog post. It’s excellent and teaching me things. As someone already familiar with functional programming I love it. I still feel like a very basic functional programmer and that post explains beautifully, without using libraries, how I can take my functional programming a step further. However I would argue it struggles to convince why someone should start to use functional programming.

    Here’s three sections of talking about the hard-to-see benefits of functional programming (emphasis mine):

    We could then put those together with pipe() like this:

    const comments = pipe(commentStrs,
        filter(noNazi),
        take(10),
        map(emphasize),
        map(itemize),
        join('\n'),
    );

    If we squint a little, our pipeline isn’t so different from chaining array methods:

    const comments = commentStrs
       .filter(noNazi)
       .slice(0, 10)
       .map(emphasize)
       .map(itemize)
       .join('\n');

    Now, someone may feel that the array method chaining looks a little cleaner. They may be right. And someone else may even be wondering why we’d waste time with pipe() and those utility functions.

    later on:

    This [non functional block of code] code is fine. For lots of people, it’s going to be familiar and readable. It accomplishes the same result as the composed version. Why would anyone bother with pipe()?

    and in the conclusion:

    Now, you may not care one whit about functional programming. That’s fine. But using pipe() opens up a whole new way to structure programs. With statements, we write code as a series of instructions to the computer. It’s a lot like a recipe in a cookbook. Do this; then do that; then do this other thing. But with composition, we express code as relationships between functions.

    I think these arguments for functional programming can be simplified and strengthened.

    Declare me a cookbook

    (its cookbooks all the way down)

    FP as I understand it is described as being like a cookbook. It’s declarative – mix this, bake that. You take the output of one part of the recipe and apply it to the next part. You don’t work on protein by protein of the egg, you whisk the whole thing. Maybe you separate the white and the yolk, but you’re always dealing with things as a whole.

    Once you start selling functional programming to people as ‘express code as relationships between functions’, I think you have lost. Either they understand what you mean, which means they already are sold, or they don’t understand in which case you will never sell it to them.

    Composition encourages us to think about code as relationships between expressions … As a result, our code becomes more declarative.

    So ‘relations between expressions’ gives us more declarative code.

    SQL

    Relate declarative code to SQL.

    In SQL, the CURSOR is the only available loop and it is seen as a code smell. WHERE (filter), aggregation functions like SUM (reduce) and any transformational functions like CONCAT in SELECT (map) are exactly what coders understand and use naturally.

    FP is dealing with your whole group of data as one block.

    Tables, not rows.

    Excel

    Excel has been used by millions of non-coders to code. It is the most powerful and most used computer platform.

    If non-programmers can understand how powerful Excel is, then programmers should understand how powerful Excel-without-borders is.

    Its just functions

    Consider the power of just writing a function:

    function double (x) { return 2 * x; }

    Its much easier than wrapping that function up in a class, but much more powerful than writing 2 * myVar everywhere.

    A beautiful balance between DRY and only getting the banana (not the gorilla and the rain forest).

    1000 years of proofs

    The other reference point I keep coming back to, is that functional programming is backed by 1000 years of mathematics. Mapping one set of data onto another is a beautiful mathematical concept. Computer science has 70 years of history, mathematics has thousands of years.

    Functional programming came about by mathematicians and computer scientists discovering things at the same time from different angles.

    Most people will never have heard of the Church-Turing thesis. In your typical OOP course, frankly in my entire Mathematics and Computer Science degree I don’t remember talking about the Church-Turing thesis, even though we did have a course on Haskell. It was only years later, I think as a part of various links that I came across from Hacker News that I learned more about Haskell, Category Theory and the Church-Turing thesis.

    What is the Church-Turing thesis? Here’s a summary (cheers ChatGPT):

    It states that any function that can be computed by an algorithm can be computed by a Turing machine. In simpler terms, it suggests that any problem that can be solved by a step-by-step procedure can also be solved by a computer program.

    Written in another way – if you can write an algorithm in your programming language, then the computer can solve it. Coding is only so popular because we know it can be calculated. Otherwise it would just be a research topic.

    This applies to regular procedural programming as much as it does to functional programming. But if we go Wikipedia we get:

    In 1933, Kurt Gödel, with Jacques Herbrand, formalized the definition of the class of general recursive functions: the smallest class of functions (with arbitrarily many arguments) that is closed under composition, recursion, and minimization, and includes zero, successor, and all projections.

    This is one of three definitions in the Church-Turing thesis that were proved to be equivalent. The other two definitions were by Alonzo Church (λ-calculus) and Alan Turing (Turning machines). But interestingly this definition is much more relevant to functional programming.

    When you are composing functions (passing the result of one function to another), when you are doing function recursion you are standing on the shoulders of Kurt Gödel, whilst Church and Turing look on approvingly. You have a clear, transparent path to proven methods.

    I feel their presence in the room when I’m coding. If you’re doing OOP, maybe you think you have the approving gaze of Alan Kay (the originator of OOP concept). But if you’re using Java, C# or C++ (and definitely if you’re using classes in JavaScript), he’s really not a fan:

    the C based languages that have been painted with “OOP paint”.

    – Alan Kay comment (2010)

    Start the FP journey

    At the most basic level, replacing loops for map, filter and reduce can be done easily. This is how I taught myself functional programming using general purpose languages. You don’t need to use compose, pipe, flow as mentioned in the blog post. You don’t need monads.

    What you need is:

    • functions as parameters
    • return functions
    • map
    • filter
    • reduce

    That will get you enough for years of coding. You can learn things like flatMap as a next step.

    I’m fine if people write lots and lots of nested functions. It may be ugly but it’s easy for anyone who isn’t familiar with FP to read.

    compose, pipe, flow similar to arrow functions can all make your code more powerful. If you have a culture that understands FP then they are great to use. They’re the next step up. What is great is that there are many more levels up that you can go – category theory is always there waiting for you to learn about. It’s amazingly powerful, but you don’t need it.

    Conclusion

    I like FP because:

    1. My SQL and my regular code become more similar (they’re declarative)
    2. Coding declaratively is “good”
    3. My thinking about my code acts on data as a whole (so my SQL thinking of sets and tables becomes more similar)
    4. Thinking about data as a whole is “good”
    5. 1) and 3) mean that I can apply the same thinking and coding all the way through my programming stack. A trick I learn in the database can be applied in the front end.
    6. Its mathematical and so the concepts I use have been proven to work. I can’t be sure we’ll be using for and while in a 1000 years, but map, filter and reduce will still be there

    Finally and for me most importantly is that I believe I have less bugs in my code. Removing just the simple off by one error in code is the gateway drug. I have less places to look for bugs in my code, so I spot bugs faster, this has a compound-interest style impact on the rest of my code. I spend less time fixing bugs and so less time having to refactor. Bugs get harder and take longer to fix the older they are. I spend more time coming up with new code, thinking about the data and solving the problem better on the first attempt.

    I spend my days building and not repairing.

  • Composable

    What does it mean to say that something is composable in JavaScript? These are some notes after watching the funfunfunction Promises video.

    Composing two functions is calling one function inside another:

    const f = x => x*x
    const g = x => x*2
    
    console.log(g(f(1)))

    The video compares callbacks:

    loadImageCallbacked('images/cat1.jpg', (error, img1) => {
        if (error) throw error
        addImg(img1.src)
        loadImageCallbacked('images/cat2.jpg', (error, img2) => {
            if (error) throw error
            addImg(img2.src)
        })
    })

    vs Promises:

    Promise.all(
        loadImage('images/cat1.jpg'),
        loadImage('images/cat2.jpg')
    ).then(images => {
        images.map(img => addImg(img.src))
    })

    Callbacks are not composable, but Promises are.

    Or in individual terms, we can return a promise from each then call until we’re done:

    loadImage('images/cat1.jpg').then(img => {
        addImg(img.src)
        return loadImage('images/cat2.jpg')
    }).then(img => {
        addImg(img.src)
        // it's a good habit to always return something from a Promise
        return null
    })

    So a callback in the simplest terms is a function g that just calls the callback f that is passed in:

    const f = x => x * x
    const g = (x, f) => {
        f(x)
    }
    console.log(g(1, f))

    Now compare this to composable functions: g(f()). We are not passing the output of f to g, we are passing f itself. The console.log will output undefined because g doesn’t return anything, it could but that’s not typically how we use callbacks.

    So now at least it makes sense to me why callbacks aren’t composable.

  • VSCode Neovim setup

    I recently switched over to using the vscode-neovim extension for VSCode.

    What wasn’t obvious though was how to get a plugin manager and plugins / vim customisations working.

    I’ll add here quickly my plugins setup as I’m using vim-surround, and a bunch of Tim Pope plugins:

    I’m on Linux / Ubuntu 22.04, with nvim installed via apt with ppa-neovim/unstable – you need this to get the current required nvim v0.8+.

    I moved from Vim to Neovim and I still use my .vimrc and amazingly this kind of setup seems to work with vscode-neovim too.

    As per the :help nvim-from-vim have the following ~/.config/nvim/init.vim:

    set runtimepath^=~/.vim runtimepath+=~/.vim/after
    let &packpath = &runtimepath
    if exists('g:vscode')
    " VSCode extension
    source ~/.vimrc.vscode
    else
    " ordinary Neovim
    source ~/.vimrc
    endif
    view raw init.vim hosted with ❤ by GitHub

    This happily loads my ~/.vimrc file for terminal nvim and then loads ~/.vimrc.vscode for vscode-neovim – which also appears to load:

    1. It sets my leader to <space>
    2. It loads Plug
    3. It loads my custom key mappings
    4. It loads vim-surround and and vim-repeat
      1. I know it loads these because I have a command map <leader>' ysiw'
      2. This puts single quotes around the current word
      3. This works (so vim-surround works)
      4. I can then ‘repeat’ my adding quotes with . which means vim-repeat is working in combination with it.

    I have massively stripped my .vimrc file down and renamed it to ~/.vimrc.vscode:

    let data_dir=has('nvim') ? stdpath('data') . '/site' : '~/.vim'
    if empty(glob(data_dir . '/autoload/plug.vim'))
    silent execute '!curl -fLo '.data_dir.'/autoload/plug.vim –create-dirs https://raw.githubusercontent.com/junegunn/vim-plug/master/plug.vim&#39;
    autocmd VimEnter * PlugInstall –sync | source $MYVIMRC
    endif
    set nocompatible
    call plug#begin('~/.vim/bundle')
    Plug 'tpope/vim-sensible'
    Plug 'tpope/vim-surround'
    Plug 'tpope/vim-unimpaired'
    Plug 'tpope/vim-repeat'
    Plug 'tpope/vim-commentary'
    call plug#end()
    nnoremap <space> <nop>
    let mapleader="\<space>"
    let g:mapleader="\<space>"
    try
    autocmd FileType php setlocal commentstring=\/\/\ %s
    autocmd FileType javascript setlocal commentstring=\/\/\ %s
    autocmd FileType reason setlocal commentstring=\/\/\ %s
    autocmd FileType dosbatch setlocal commentstring=rem\ %s
    autocmd FileType rust setlocal commentstring=//\ %s
    catch
    endtry
    map <leader>' ysiw'
    map <leader>" ysiw"
    map <leader>; A;<esc>
    map <silent> <leader><cr> :nohlsearch<cr>
    nnoremap <leader>bb :buffers<cr>:b<space>
    map <leader>s :w<cr>
    view raw .vscode.vimrc hosted with ❤ by GitHub

    Some interesting things that do work:

    • vim-plug works!
    • Basically it’s just really really cool that you can use a .vimrc
      • This means almost tons of remaps should work
    • :buffers works but it’s kind of ugly
    • :nohlsearch works (removing the highlight)
    • :vsplit works and moving with <C-w>[hjkl]

    Lots of things don’t work like:

    • I got a conflict between my vim-plug config for VSCode and for neovim
      • By running :PlugClean inside VSCode this wiped all my neovim vim-plug directories
      • Effectively I think this means its better to maintain your plugins via neovim
      • Then use a subset within VSCode
    • preview, quickfix and location windows
    • I don’t think :windo diffthis works
    • You have the same problem as with VSCode Vim that undoing all changes doesn’t get rid of the file ‘dirty bit’ so you have to save it to fully undo
    • :bd doesn’t work as you expect – you need to use :q instead
    • I found the :e <type file path> didn’t work with auto-complete beyond the current directory – just use Ctrl + P instead.
    • There is no command history – you can’t use the up arrow to go to previous ex commands that you typed – I’m surprised about this so maybe there is a config setting somewhere Ctrl + N/Ctrl + P are used instead of up/down

    I’ll try to list more as I go further.

    For a couple of hours spent setting it up and to have 90% of the plugins I need working is really great.

    Until I can get fugitive and vim diffs (in combination with fugitive) working I will still want to use terminal nvim, but that fits quite easily into my coding process for now.

  • Javascript REPL

    I really like the simple ‘console’ REPL that you have in a browser debug tools. I wanted to recreate this in VS Code.

    tl;dr Debug console

    It turns out after lots of experimenting this can be also done with the ‘Debug Console’ when you start a debug session – see VSCode debugging.

    This is exactly what I wanted.

    However I had tried a whole bunch of REPL plugins first.

    Node.js Interactive window (REPL)

    https://marketplace.visualstudio.com/items?itemName=lostfields.nodejs-repl

    This is also a nice solution but seemed lacking compared to the browser console because you can’t inspect the objects so easily. But I guess it’s more like a standard REPL.

    One problem is that it hasn’t been developed for years.

    You have to disable eslint at the top

    /* eslint-disable */

    This seems more like a repl than the playground – it evals immediately

    Interactive Javascript playground

    https://github.com/axilleasiv/vscode-javascript-repl-docs

    Very similar to the above plugin – neither is particularly actively maintained

    This does seem to be very nice though.

    You have to disable eslint at the top

    /* eslint-disable */

    This allows you to do more like a playground where you can eval immediately or just eval with //= comments after a line

    You can run a REPL on a markdown file too: https://github.com/axilleasiv/vscode-javascript-repl-docs/wiki/Markdown-code-blocks

    Code Runner

    By far the most installed plugin is https://github.com/formulahendry/vscode-code-runner. This works for any language but has support for Node.

    It’s kind of ugly though and it’s more like a SQL prompt where you can run a line or two of code and get output.

    Ramda

    https://ramdajs.com/repl/

    This seems really interesting – you can install it locally too. This is probably the closest that I am looking for.

    But you have to do quite a lot of installation locally.

    Jupyter notebooks

    Initially I was left cold by the REPLs as I didn’t have much access to the values – I liked the interactivity of the browser console.

    My next step was to try Jupyter notebooks with a node.js kernal.

    This led me to: https://github.com/DonJayamanne/typescript-notebook

    This recommends installing Jupyter which adds a whole ton of stuff to VS Code but it all seems quite cool.

    You can start in pseudo REPL mode where you just keep running a single line of code.

    Or you can properly generate a ‘node notebook’ *.nnb file that you can use as a scratch pad. This then gives you full notebook support – this might be interesting for debug logs. I could create a JIRA-XXX.nnb notebook for each issue – then attach this to the Jira issue. Similar to the vim logs.


    Note: You need to disable Vim mode for the nnb file

    Then you have nice shortcuts you can use:

    • b – create new run section below
    • enter – focus in the section (like INSERT mode for Vim)
    • esc – lose focus on the section (like NORMAL mode for Vim)
    • shift+enter – run the section
    • j,k – move up and down sections
    • dd – delete section

    It also nicely shows up functions that you have created inside the notebook in the intellisense.